Orchestrate dbt with Airflow on Spark: A Complete Guide
How do I run dbt on Spark with Airflow?
Install Ilum with the Spark SQL (Thrift) server and Airflow on the 3.1.1-dbt image:
helm install ilum ilum/ilum \
  --set ilum-hive-metastore.enabled=vrai \
  --set ilum-core.metastore.enabled=true \
  --set ilum-core.metastore.type=hive \
  --set ilum-core.sql.enabled=true \
  --set ilum-sql.enabled=true \
  --set airflow.enabled=true \
  --set airflow.images.airflow.tag=3.1.1-dbt
An example dbt project is pre-loaded and synced to Airflow, where Astronomer Cosmos generates one task per dbt model and test. Trigger the ilum_dbt_thrift_pipeline DAG: the models run on the Ilum Spark cluster through the spark_thrift_default connection on port 10009.
This guide demonstrates how to orchestrate scalable dbt pipelines on Ilum's Apache Spark cluster using Flux d’air Apache et Astronomer Cosmos. You will learn how to build a robust medallion architecture (Bronze → Silver → Gold) utilizing Kubernetes-native compute for efficient data transformation. We will cover automatic DAG generation, data quality testing, and incremental processing strategies.
For a comprehensive deep-dive into the architecture, benefits, and strategic considerations of running dbt on Spark with Airflow, see our detailed blog post: Orchestrate dbt on Spark with Airflow: A Guide to Modern Data Engineering on Ilum.
Prerequisites for Airflow and dbt on Ilum
- Ilum version 6.6.2 or later
- Airflow enabled with the
3.1.1-dbtimage - Spark SQL (Thrift Server) or Spark Connect Activé
- Basic familiarity with dbt and Airflow concepts
dbt-Airflow-Spark Architecture Overview
The integration combines four key components:
| Component | Technology |
|---|---|
| Compute Engine | Apache Spark on Ilum (Kubernetes-native) |
| Data Modeling | dbt-spark (dbt-core + Spark adapter) |
| Orchestration | Apache Airflow 3.1 with KubernetesExecutor |
| DAG Generation | Astronomer Cosmos |
Workflow: Git repository → gitSync → Airflow → Cosmos (auto-generates DAG) → Spark SQL / Spark Connect → Ilum Spark Cluster
Quick Start: Deploying dbt Pipelines
1. Enable Airflow with dbt Support
Install Ilum with Airflow and dbt pre-configured:
helm install ilum ilum/ilum \
  --set ilum-hive-metastore.enabled=vrai \
  --set ilum-core.metastore.enabled=true \
  --set ilum-core.metastore.type=hive \
  --set ilum-core.sql.enabled=true \
  --set ilum-sql.enabled=true \
  --set airflow.enabled=true \
  --set airflow.images.airflow.tag=3.1.1-dbt
When using the 3.1.1-dbt image tag, the complete dbt project and DAG described in this guide are automatically pre-loaded into the internal Gitea repository and synced to Airflow. You can trigger the example pipeline immediately after installation.
2. Access Airflow
Navigate to the Airflow UI via the Ilum console. The default credentials are typically admin :admin.
3. Verify the Connection
Starting from Ilum 6.6.2le spark_thrift_default connection is automatically configured. Verify it exists:
Admin → Connections → Search for spark_thrift_default
If missing, create it manually:
| Field | Valeur |
|---|---|
| Connection ID | spark_thrift_default |
| Connection Type | Étincelle ou spark_sql |
| Host | ilum-sql-thrift-binary.<NAMESPACE>.svc.cluster.local |
| Port | 10009 |
4. Trigger the DAG
Find ilum_dbt_thrift_pipeline in the Airflow UI and trigger it manually. Monitor the Graph View to see the auto-generated task dependencies.
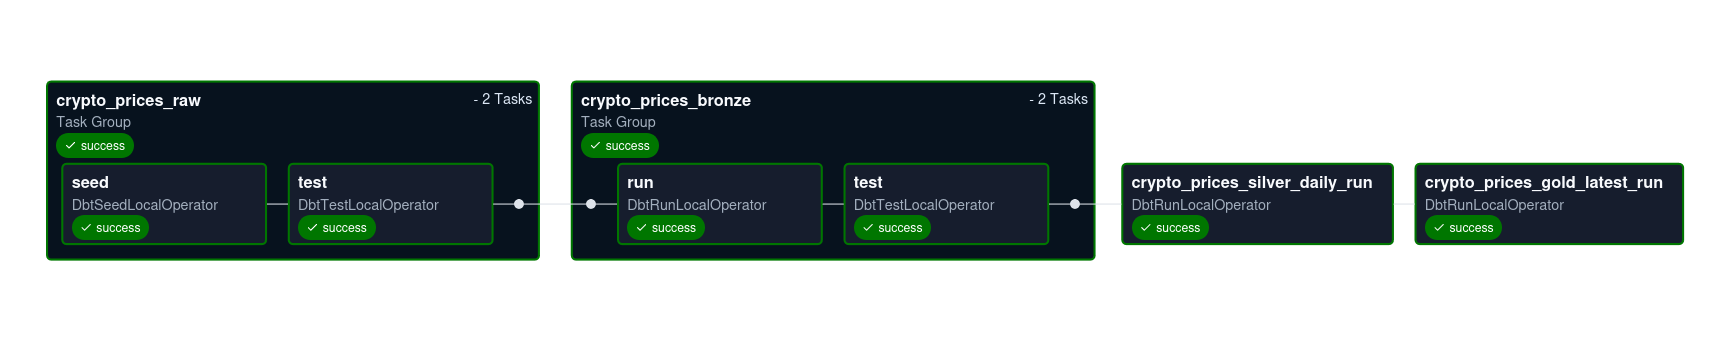 The Airflow DAG automatically generated by Astronomer Cosmos, reflecting the dbt model dependencies.
Project Structure
The dbt project follows a standard medallion architecture:
ilum_dbt_project/
├── dbt_project.yml
├── packages.yml
├── seeds/
│   └── crypto_prices_raw.csv
└── models/
    ├── bronze/
    │   └── crypto_prices_bronze.sql
    ├── silver/
    │   └── crypto_prices_silver_daily.sql
    ├── gold/
    │   └── crypto_prices_gold_latest.sql
    └── schema.yml
dbt Configuration
dbt_project.yml
The central configuration file defines project metadata, paths, and layer-specific settings:
nom: "ilum_dbt_project"
Version: "1.0.0"
config-version: 2

profile: "ilum_dbt_project"   # must match ProfileConfig.profile_name

model-paths: ["models"]
seed-paths: ["seeds"]
macro-paths: ["macros"]
test-paths: ["tests"]

models:
  ilum_dbt_project:
    +materialized: table
    bronze:
      +tags: ["bronze"]
    silver:
      +tags: ["silver"]
    gold:
      +tags: ["gold"]

seeds:
  ilum_dbt_project:
    +column_types:
      date: date
      symbol: corde
      price_usd: double
      volume_usd: double
      market_cap_usd: double
    crypto_prices_raw:
      +pre-hook:
        - "{{ drop_this_seed() }}"
Key features:
- Tags enable selective execution:
dbt run --select tag:gold - Column types ensure correct Spark table schemas
- Pre-hook
drop_this_seed()provides idempotent seed loading for demos
Medallion Architecture Layers
Bronze Layer: Type Normalization
File: models/bronze/crypto_prices_bronze.sql
Converts raw seed data into typed, normalized tables with incremental processing:
{{ config(
    Matérialisée='incremental',
    unique_key=['date', 'symbol']
) }}

select
  cast(date comme date)         comme date,
  upper(symbol)              comme symbol,
  cast(price_usd comme double)  comme price_usd,
  cast(volume_usd comme double) comme volume_usd,
  cast(market_cap_usd comme double) comme market_cap_usd
De {{ réf('crypto_prices_raw') }}

{% si is_incremental() %}
where date > (select max(date) De {{ this }})
{% endif %}
Avantages:
- Only processes new records after initial load
- Reduces compute costs for large datasets
Silver Layer: Data Enrichment
File: models/silver/crypto_prices_silver_daily.sql
Adds 7-day moving averages using Spark window functions:
{{ config(Matérialisée='Table') }}

select
  date,
  symbol,
  price_usd,
  volume_usd,
  market_cap_usd,
  Avg(price_usd) over (
    partition par symbol
    order par date
    rows entre 6 preceding et current ramer
  ) comme price_usd_7d_avg,
  Avg(volume_usd) over (
    partition par symbol
    order par date
    rows entre 6 preceding et current ramer
  ) comme volume_usd_7d_avg
De {{ réf('crypto_prices_bronze') }}
Gold Layer: Business-Ready Views
File: models/gold/crypto_prices_gold_latest.sql
Produces analytics-ready data showing the latest 30 days per symbol:
{{ config(Matérialisée='Table') }}

avec ranked comme (
  select
    *,
    row_number() over (
      partition par symbol
      order par date desc
    ) comme rn
  De {{ réf('crypto_prices_silver_daily') }}
)

select
  date,
  symbol,
  price_usd,
  price_usd_7d_avg,
  volume_usd_7d_avg,
  market_cap_usd
De ranked
where rn <= 30
Data Quality Tests
Define tests in models/schema.yml to create quality gates:
Version: 2

seeds:
  - nom: crypto_prices_raw
    columns:
      - nom: date
        tests: [not_null]
      - nom: symbol
        tests: [not_null]
      - nom: price_usd
        tests: [not_null]

models:
  - nom: crypto_prices_bronze
    description: "Bronze layer - typed and normalized crypto prices."
    columns:
      - nom: date
        tests: [not_null]
      - nom: symbol
        tests: [not_null]
      - nom: price_usd
        tests: [not_null]
In Airflow: Cosmos converts each test into a separate task that blocks downstream models if it fails.
Generating Airflow DAGs with Cosmos
- Option A: Spark Thrift Server
- Option B: Spark Connect
File: dags/ilum_dbt_thrift.py
De DateHeure importation DateHeure, timedelta
importation os
De airflow.configuration importation Conf
De cosmos importation DbtDag, ProjectConfig, ProfileConfig, ExecutionConfig
De cosmos.profiles importation SparkThriftProfileMapping

DAGS_FOLDER = Conf.Avoir("core", "dags_folder")
DBT_PROJECT_PATH = os.chemin.join(DAGS_FOLDER, "ilum_dbt_project")
DBT_BIN = "/home/airflow/.local/bin/dbt"

profile_config = ProfileConfig(
    profile_name="ilum_dbt_project",
    target_name="prod",
    profile_mapping=SparkThriftProfileMapping(
        conn_id="spark_thrift_default",
        profile_args={
            "schema": « par défaut »,
            "threads": 4,
        },
    ),
)

dbt_dag = DbtDag(
    project_config=ProjectConfig(
        dbt_project_path=DBT_PROJECT_PATH,
    ),
    profile_config=profile_config,
    execution_config=ExecutionConfig(
        dbt_executable_path=DBT_BIN,
    ),
    dag_id="ilum_dbt_thrift_pipeline",
    schedule="@daily",
    start_date=DateHeure(2024, 1, 1),
    catchup=False,
    default_args={
        "owner": "data-team",
        "retries": 2,
        "retry_delay": timedelta(minutes=5),
    },
)
How it works:
SparkThriftProfileMappinguses the Airflow connectionspark_thrift_default- Cosmos scans the dbt project and auto-generates tasks for each model, seed, and test
- Dependencies mirror dbt's
ref()relationships
File: dags/ilum_dbt_connect.py
De DateHeure importation DateHeure, timedelta
importation os
De airflow.configuration importation Conf
De cosmos importation DbtDag, ProjectConfig, ProfileConfig, ExecutionConfig
De cosmos.profiles importation SparkSessionProfileMapping

DAGS_FOLDER = Conf.Avoir("core", "dags_folder")
DBT_PROJECT_PATH = os.chemin.join(DAGS_FOLDER, "ilum_dbt_project")
DBT_BIN = "/home/airflow/.local/bin/dbt"

profile_config = ProfileConfig(
    profile_name="ilum_dbt_project",
    target_name="prod",
    profile_mapping=SparkSessionProfileMapping(
        conn_id="spark_connect_default",
        profile_args={
            "schema": « par défaut »,
            "threads": 4,
        },
    ),
)

dbt_dag = DbtDag(
    project_config=ProjectConfig(
        dbt_project_path=DBT_PROJECT_PATH,
    ),
    profile_config=profile_config,
    execution_config=ExecutionConfig(
        dbt_executable_path=DBT_BIN,
    ),
    dag_id="ilum_dbt_connect_pipeline",
    schedule="@daily",
    start_date=DateHeure(2024, 1, 1),
    catchup=False,
    default_args={
        "owner": "data-team",
        "retries": 2,
        "retry_delay": timedelta(minutes=5),
    },
)
How it works:
-
SparkSessionProfileMappinguses the Airflow connectionspark_connect_default -
Cosmos scans the dbt project and auto-generates tasks for each model, seed, and test
-
Dependencies mirror dbt's
ref()relationshipsSpark Connect Connection:
Field Valeur Connection ID spark_connect_defaultHost job-<id>-driver-svc.<NAMESPACE>.svc.cluster.localPort 15002Extra {"connect": "sc://job-<id>-driver-svc.<NAMESPACE>.svc.cluster.local:15002"}
Thrift vs Spark Connect
| Aspect | Thrift Server | Spark Connect |
|---|---|---|
| Endpoint | Central SQL server (shared) | Per-job endpoint (isolated) |
| Use case | Multiple tools sharing one endpoint | Isolated compute per project |
| Protocol | JDBC/Thrift | gRPC (native Spark API) |
| Connection | Stable service name | Dynamic job-based URL |
Tracking Data Lineage and Dependencies
Once the pipeline runs successfully, tables are stored in the Hive Metastore and accessible across Ilum components:
- Ilum SQL: Query tables directly
- Carnets Jupyter: Analyze data interactively
- Emplois Spark: Use as input for other pipelines
- Lineage View: Visualize table dependencies in Ilum UI
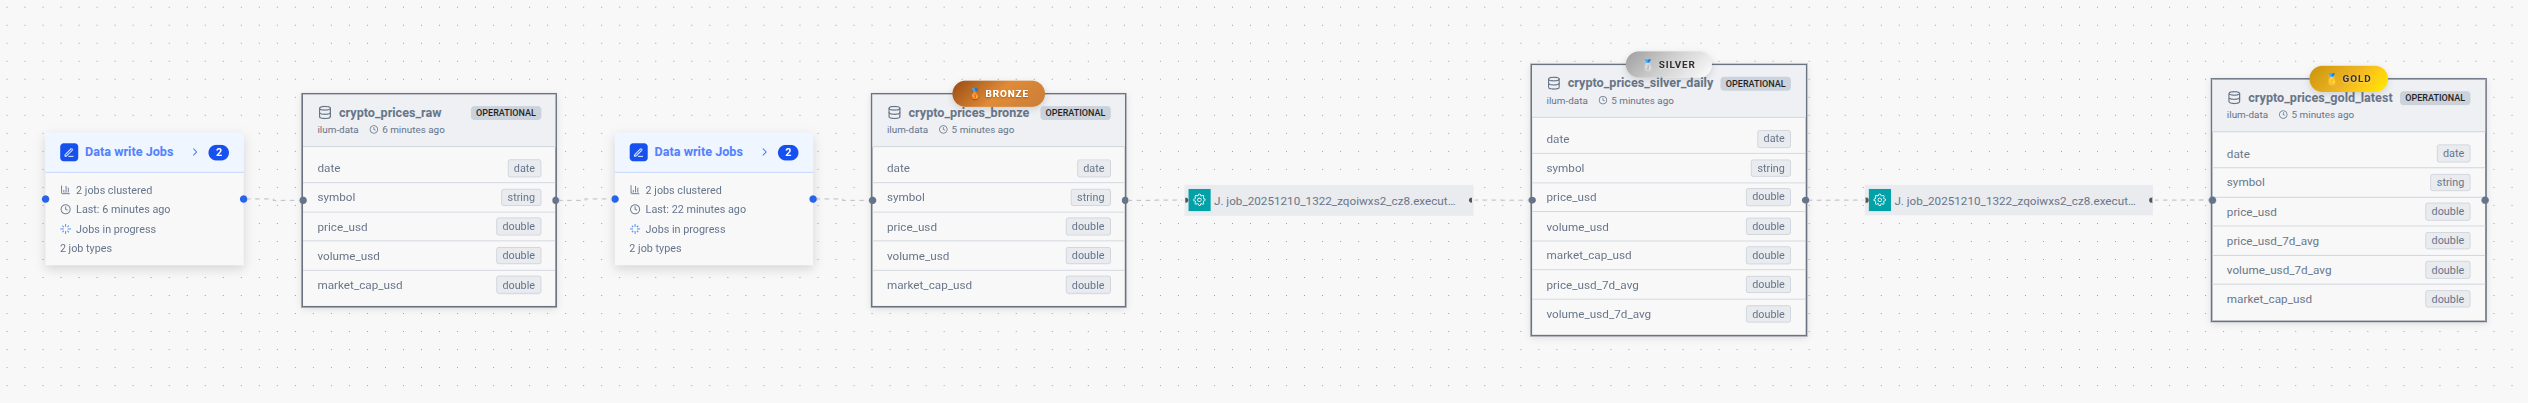 Figure 2: The Ilum Data Lineage view visualizing the full medallion architecture (Bronze → Silver → Gold) and table dependencies.
Principaux avantages
| Caractéristique | Benefit |
|---|---|
| No dbt Cloud | Fully open-source, no subscription costs |
| Medallion pattern | Clean data architecture (bronze → silver → gold) |
| Incremental models | Process only new data, reduce compute costs |
| Quality gates | dbt tests block downstream if data fails |
| KubernetesExecutor | Each task isolated in separate pod |
| gitSync | Code changes auto-deployed from Gitea |
| Auto DAG generation | Cosmos creates tasks from dbt models automatically |
| Full lineage | Track model dependencies in Airflow UI and Ilum |
Dépannage
Click to view troubleshooting steps
Connection Errors
If you see failed to resolve sockaddr errors in dbt logs:
[Errno -2] Name or service not known
Solution: Verify the Thrift service exists:
kubectl get svc -n <NAMESPACE> | grep thrift
Ensure the connection host matches the service name exactly.
DAG Not Appearing
If the DAG doesn't show up in Airflow:
- Check gitSync logs to ensure the dbt project is synced
- Verify the
DBT_PROJECT_PATHpoints to the correct directory - Look for parsing errors in Airflow logs
Tests Failing
If dbt tests fail unexpectedly:
- Check the test task logs in Airflow
- Query the table directly via Ilum SQL to verify data quality
- Adjust test thresholds or fix upstream data issues
Foire aux questions
Which dbt adapter is used to run dbt on Spark?
The pipeline uses dbt-spark, dbt-core with the Spark adapter. It connects either to the Spark Thrift Server (ilum-sql-thrift, port 10009) or to a Spark Connect endpoint (port 15002), and the SQL runs on the Ilum Spark cluster.
Should dbt connect through the Thrift Server or Spark Connect?
The Thrift Server is a central, shared SQL endpoint with a stable service name, suited to several tools using one endpoint. Spark Connect provides an isolated, per-job endpoint over gRPC, suited to dedicated compute per project. See Thrift vs Spark Connect.
How are Airflow DAGs created from a dbt project?
Astronomer Cosmos parses the dbt project and generates an Airflow DAG with one task per model and per test, preserving ref() dependencies. A failing test blocks the downstream models.
Is dbt Cloud required?
No. The stack is fully open source: dbt-core, dbt-spark, Apache Airflow and Astronomer Cosmos running on Kubernetes, without a dbt Cloud subscription.
Which Ilum version is required?
Ilum 6.6.2 or later. From 6.6.2 the spark_thrift_default Airflow connection is configured automatically.
Ressources additionnelles
- Blog Post: Orchestrate dbt on Spark with Airflow - Comprehensive guide with architecture details and strategic benefits
- Astronomer Cosmos Documentation
- dbt-spark Adapter